
Answers in your context
Models trained on your proprietary data give accurate, context-aware responses for your customers and processes.
LLM training · Data to benchmark
Training a language model well is an engineering task: the right data, a pipeline that uses compute efficiently, and proof that the model works before it reaches production. We curate your datasets, build distributed training pipelines, tune hyperparameters and benchmark the result on real-world test cases.
Training decides how accurate, efficient and reliable your model is in day-to-day use.
Models trained on your proprietary data give accurate, context-aware responses for your customers and processes.
Scalable pipelines and systematic hyperparameter tuning make the most of computing resources and reduce costs.
Validation with standard metrics and real-world benchmarks confirms accuracy, efficiency and robustness before deployment.
The full training cycle, from raw data to a validated model that stays current.
We preprocess and curate large, diverse datasets, with cleaning and data augmentation to improve accuracy and contextual understanding.
End-to-end pipelines built for your needs, using distributed computing, cloud environments and high-performance GPUs to speed up training.
We adapt pre-trained models with your domain-specific data for better accuracy and relevance.
We test and adjust parameters systematically to improve training efficiency, reduce overfitting and help the model generalise.
We evaluate trained models against standard metrics and real-world benchmarks before they go live.
Data security and compliance measures protect sensitive training datasets throughout the process.
We help deploy the trained model into production and integrate it with your workflows and applications.
We monitor performance and update the model with new data, so it stays accurate and relevant over time.
Not sure which of these you need? Describe the problem and we will recommend the approach.
Discuss your project
In-house LLMno reliance on third-party LLM services
A private, hosted chatbot built on a custom large language model, giving a consulting firm answers with source references while keeping full control over its data.
Read the case study
1 week of analyst work saved per new niche market
An end-to-end NLP solution that lets private equity funds and venture capital firms find and cluster relevant companies by meaning rather than by industry code or keyword.
25x faster invoice processing
A web service that extracts data from different types of invoices, automating data entry for a multinational equipment distributor and saving 850 man-hours per month.
~10,000 man-hours saved
An interactive NLP tool that assesses employees' skills, compares skill profiles and identifies skill gaps between business-critical staff and their potential successors.
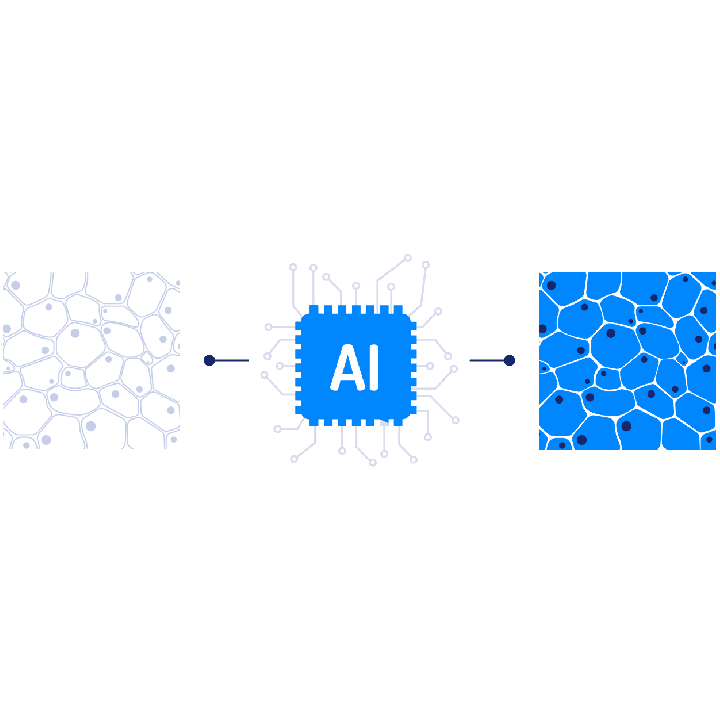
Reused one disease classifier across stain reagents
An AI component that translates histological images from one stain domain to another, so existing software and machine learning models can be reused across all reagents.
Many vendors can build a demo. Making AI work reliably on real data, inside real business processes, takes a different kind of team. This is what you get with us.
AI Superior was founded in 2019 by AI researchers with published papers and patents. That depth runs through the whole team.
Every project is de-risked in stages, with a go/no-go decision at each milestone, so budget goes only into solutions proven on your data.
Strategy, models and software are designed together, not handed over between separate vendors.
When data must not leave your organisation, we build on private, self-hosted models instead of third-party AI services.
Your project is led by senior data scientists and engineers with research backgrounds, supported by our product and development teams.
 Dr. Sergey Sukhanov Chief Data Scientist
PhD in Machine Learning, data scientist since 2013. Publications, patents and 30+ implemented AI use cases; several IEEE awards.
 Dr. Ivan Tankoyeu Chief Data Officer
PhD in Computer Science. Recognised by the IEEE GRSS Society, winner of the Global AI Hackathon 2017, Kaggle TOP500 data scientist (2014).
 Sergio Frayle, M.Sc. Lead Data Scientist
Master’s in AI, Pattern Recognition and Digital Imaging; 7+ years in image processing and computer vision, with publications.
 Enrique Fernández, M.Sc. Senior ML Expert
Master’s in Robotics and Mechatronics; builds and deploys complex AI solutions, particularly in computer vision and NLP.
 Peter Luck, M.Sc. AI Consultant
Master’s in Business Engineering and Computer Science; product and project manager for machine-learning products.
“AI Superior showed a strong commitment to delivering high-quality solutions to us.”
Improves and maintains the data infrastructure of a credit solutions company: data pipelines, ML models and custom reports.
“AI Superior responded to all of our needs very carefully and considered them in the project.”
Built AI models and a dashboard for a pilot program that detects waste in drone imagery.
“They delivered an extra module that we were not expecting but turned out to be very useful.”
Research and custom software development applying generative adversarial networks for a pharmaceutical company with 5,000+ employees.
Every stage ends with a result you can check. You never commit to the next stage before seeing the previous one work, so scope, budget and risk stay under your control.
We work through the business problem with your team and define the direction of the solution.
You get: Scope, approach and a high-level estimate of effort and expected results
We get to know your team and data and check whether AI is the right tool for this problem.
You get: A data assessment and a clear feasibility verdict before any build starts
We start small, using the data already available, to test the solution in practice.
You get: Measured results on your own data and a basis for the investment decision
We integrate the solution into your existing systems, fine-tune the models and adjust them where needed.
You get: A solution running inside your processes, compatible with your data and systems
Together we evaluate the results of the implementation and make sure they are interpreted correctly.
You get: A clear picture of the value delivered and where to improve next
We tailor datasets, workflows and training to the needs of each sector.
Models trained on financial data and documents.
Models for clinical and patient-facing tasks.
Models that improve how customers find and buy products.
Models trained on contracts, case material and regulation.
Models that write and optimise content in your voice.
Recognised by international business awards and by independent B2B platforms that rank companies on verified client reviews.
 Go Global Awards Winner 2021 · International Trade Council
 Best Data Science & AI Service Provider, Europe 2021 · German Business Awards
 Top Artificial Intelligence Company 2023 · Clutch
 Top Machine Learning Company 2023 · Clutch
 Clutch Champion Fall 2023 · Clutch
 Clutch Global Fall 2023 · Clutch
 Top BI & Big Data Company Germany 2023 · Clutch
 Top IT Services Company Germany 2023 · Clutch
 Top Artificial Intelligence Companies 2023 · TrueFirms
 Top Machine Learning Companies 2021 · Techreviewer
 Most Reviewed IT Services Companies Germany · The Manifest
Training covers the full process of developing a model on large datasets with substantial computing resources. Fine-tuning adapts an existing pre-trained model with your domain-specific data. We advise which route fits your goals and often combine both.
A model trained on your proprietary data is more accurate and more efficient for your tasks, whether that is an AI assistant for your customers, industry-specific document analysis or a multilingual system.
Yes. We tailor the training datasets, workflows and fine-tuning to your industry’s requirements and your business objectives.
We use encryption, access controls and compliance measures to protect sensitive information throughout training.
We validate it with standard metrics, real-world test cases and benchmarks before deployment, and keep monitoring its performance in production.
It depends on data complexity, model size and computing requirements. We put together a training plan and estimate based on your requirements.
Contact us to discuss your training needs. We propose a tailored strategy for developing, fine-tuning and deploying your model.
Share a few details and our AI team will take it from there. Here is what happens next:
Prefer to pick a time yourself?
Schedule a call