
Higher model accuracy
Precisely labelled data sets help models recognise patterns reliably in tasks such as image recognition, sentiment analysis and speech-to-text.
Data annotation · Training data for AI
A model is only as accurate as the data it learns from. We label images, video, text, audio and 3D point clouds to the specification of your model, combining AI-assisted tools with human review and quality control, and deliver data sets that plug straight into your machine learning pipeline.
Poor labels lead to inaccurate outputs. We treat annotation as part of model development, not a separate chore.
Precisely labelled data sets help models recognise patterns reliably in tasks such as image recognition, sentiment analysis and speech-to-text.
AI-assisted tools, human expertise and quality control keep labels precise and consistent, even across large data sets.
From image classification to named entity recognition and video frame annotation, the labelling scheme follows your model's requirements.
Annotation for every major data type, with the quality control to back it.
Bounding boxes, polygons, keypoints and pixel-precise semantic segmentation for object detection and image recognition.
Frame-level annotation that teaches models to track objects, actions and behavioural patterns.
Named entity recognition, sentiment analysis, intent classification and text categorisation for search, chatbots and analytics.
Phonetic and language-specific transcription, speaker identification, emotion detection and noise classification for voice recognition.
Structured annotation of LiDAR and 3D sensor data for autonomous systems, drones and geospatial models.
Complex labelling schemes for models that need several categories per item.
Multi-layered checks: AI-powered validation, human review and automated consistency checks.
Annotation workflows and guidelines designed around your model, your industry and your development pipeline.
Annotation processes designed to reduce bias and support fair model training.
Cloud-based annotation platforms and automation tools for high-volume training projects.
Not sure which of these you need? Describe the problem and we will recommend the approach.
Discuss your project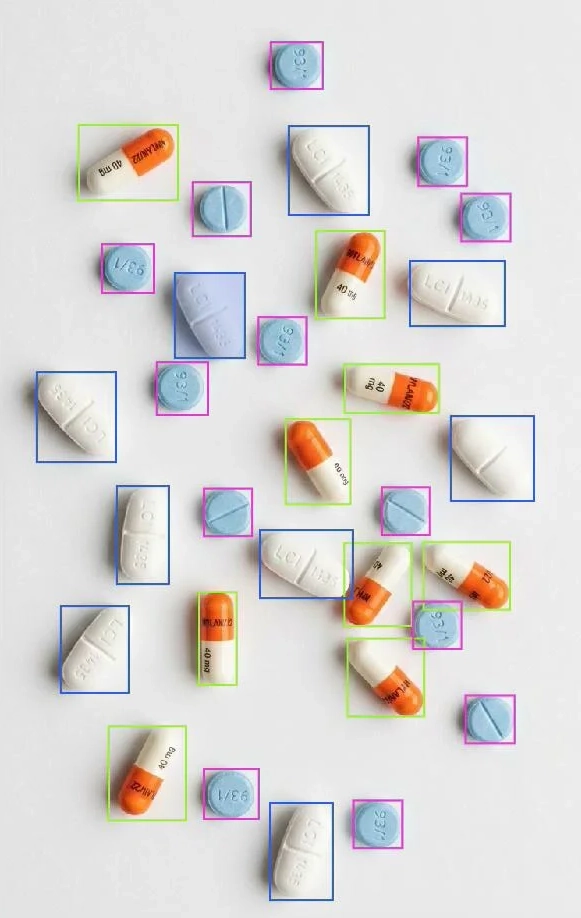
99.9%precision, recall and F1 across all predictions
A computer vision system that identifies, classifies and counts pharmaceutical pills by National Drug Code (NDC) from photos, replacing error-prone manual counting.
Read the case study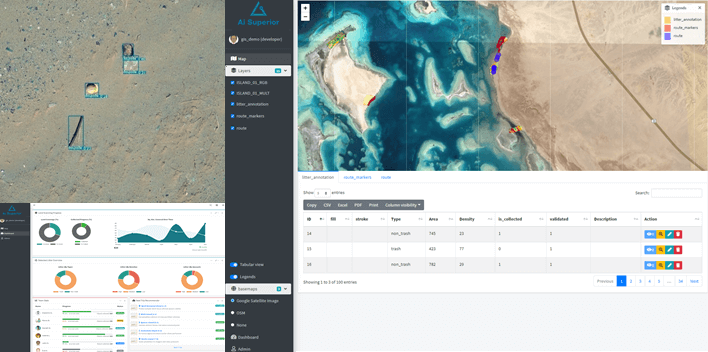
25x faster litter detection, with overall costs halved
A computer vision system that detects litter in drone images across roughly one thousand square kilometres of coastline, with a GIS application for planning and tracking collection.
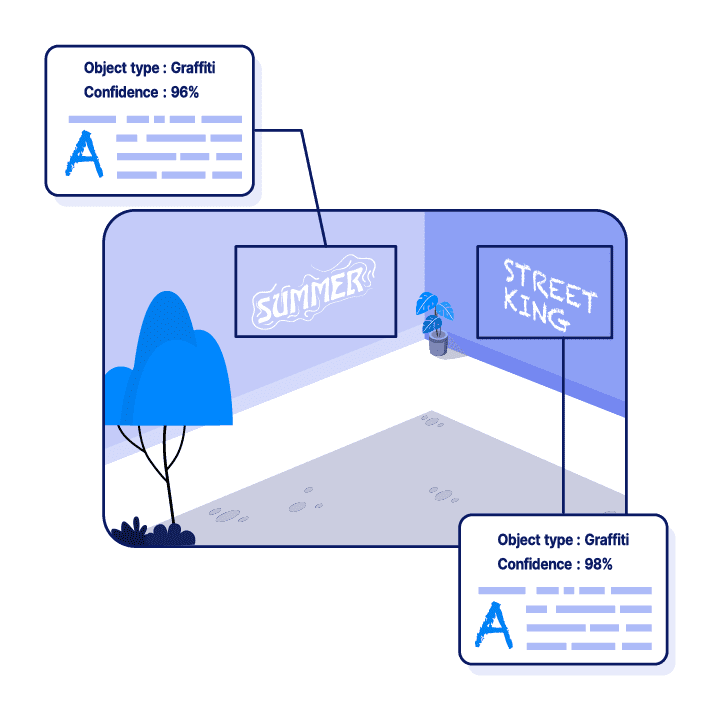
Real-time graffiti detection with GPS location
A deep learning system that detects and locates graffiti across a city in real time, so cleaning teams can find, prioritise and remove it faster.
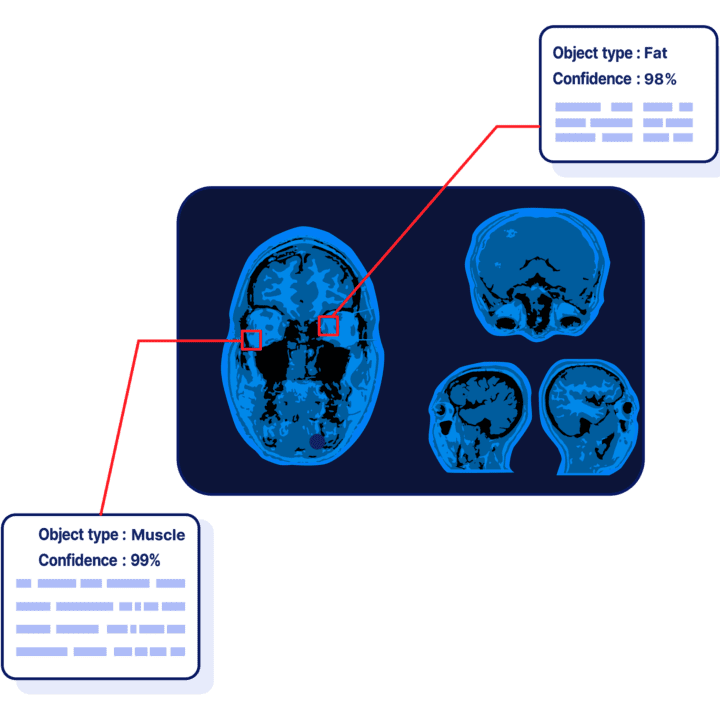
Automated fat and muscle segmentation in every MRI slice
A deep learning model for an ophthalmology centre that segments fat and muscle tissue in MRI orbit scans, estimates their volume and supports before-and-after comparisons.
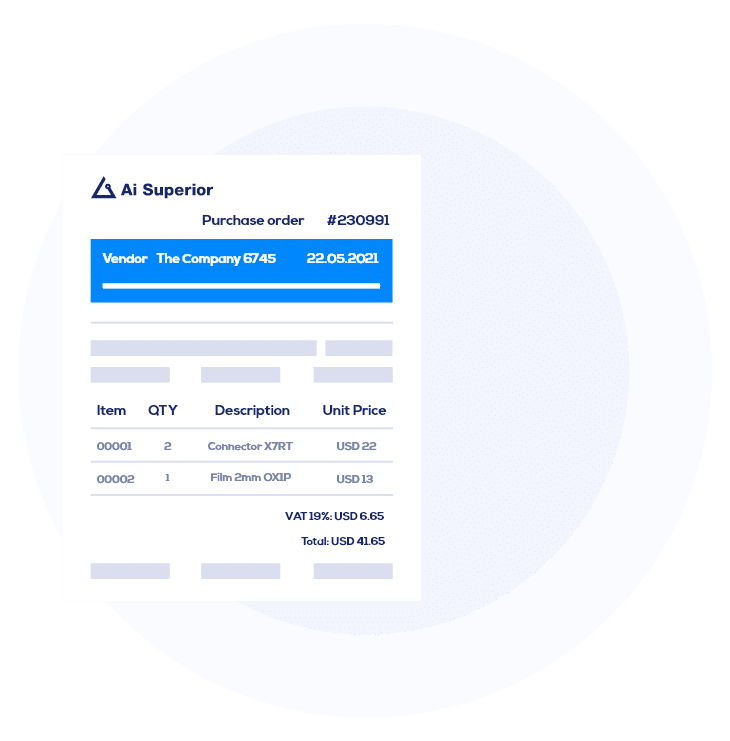
25x faster invoice processing
A web service that extracts data from different types of invoices, automating data entry for a multinational equipment distributor and saving 850 man-hours per month.
Many vendors can build a demo. Making AI work reliably on real data, inside real business processes, takes a different kind of team. This is what you get with us.
AI Superior was founded in 2019 by AI researchers with published papers and patents. That depth runs through the whole team.
Every project is de-risked in stages, with a go/no-go decision at each milestone, so budget goes only into solutions proven on your data.
Strategy, models and software are designed together, not handed over between separate vendors.
When data must not leave your organisation, we build on private, self-hosted models instead of third-party AI services.
Your project is led by senior data scientists and engineers with research backgrounds, supported by our product and development teams.
 Dr. Sergey Sukhanov Chief Data Scientist
PhD in Machine Learning, data scientist since 2013. Publications, patents and 30+ implemented AI use cases; several IEEE awards.
 Dr. Ivan Tankoyeu Chief Data Officer
PhD in Computer Science. Recognised by the IEEE GRSS Society, winner of the Global AI Hackathon 2017, Kaggle TOP500 data scientist (2014).
 Sergio Frayle, M.Sc. Lead Data Scientist
Master’s in AI, Pattern Recognition and Digital Imaging; 7+ years in image processing and computer vision, with publications.
 Enrique Fernández, M.Sc. Senior ML Expert
Master’s in Robotics and Mechatronics; builds and deploys complex AI solutions, particularly in computer vision and NLP.
 Peter Luck, M.Sc. AI Consultant
Master’s in Business Engineering and Computer Science; product and project manager for machine-learning products.
“They successfully fulfilled every component of the project and exceeded our expectations.”
Built an AI model that analyzes the roofs of residential and commercial properties, including data collection and labeling. All key deliverables were completed on time.
“AI Superior responded to all of our needs very carefully and considered them in the project.”
Built AI models and a dashboard for a pilot program that detects waste in drone imagery.
“AI Superior showed a strong commitment to delivering high-quality solutions to us.”
Improves and maintains the data infrastructure of a credit solutions company: data pipelines, ML models and custom reports.
Every stage ends with a result you can check. You never commit to the next stage before seeing the previous one work, so scope, budget and risk stay under your control.
We work through the business problem with your team and define the direction of the solution.
You get: Scope, approach and a high-level estimate of effort and expected results
We get to know your team and data and check whether AI is the right tool for this problem.
You get: A data assessment and a clear feasibility verdict before any build starts
We start small, using the data already available, to test the solution in practice.
You get: Measured results on your own data and a basis for the investment decision
We integrate the solution into your existing systems, fine-tune the models and adjust them where needed.
You get: A solution running inside your processes, compatible with your data and systems
Together we evaluate the results of the implementation and make sure they are interpreted correctly.
You get: A clear picture of the value delivered and where to improve next
Examples of the labelled data sets we prepare for models in each sector.
Labelled data for fraud detection, claims automation and risk assessment.
Precise annotation for fraud detection, investment analysis and customer profiling.
Labelled medical data sets for drug discovery and patient monitoring.
Labelled data for site safety, predictive maintenance and planning.
Annotated data for valuation, search and document processing.
Annotated geospatial and sensor data for exploration and operations.
Annotation for content moderation, sentiment and recommendations.
Labelled data for document automation and citizen services.
Training data for support automation, analytics and personalisation.
Annotation for satellite imaging and anomaly detection.
Annotated data for impact assessment and donor engagement.
Recognised by international business awards and by independent B2B platforms that rank companies on verified client reviews.
 Go Global Awards Winner 2021 · International Trade Council
 Best Data Science & AI Service Provider, Europe 2021 · German Business Awards
 Top Artificial Intelligence Company 2023 · Clutch
 Top Machine Learning Company 2023 · Clutch
 Clutch Champion Fall 2023 · Clutch
 Clutch Global Fall 2023 · Clutch
 Top BI & Big Data Company Germany 2023 · Clutch
 Top IT Services Company Germany 2023 · Clutch
 Top Artificial Intelligence Companies 2023 · TrueFirms
 Top Machine Learning Companies 2021 · Techreviewer
 Most Reviewed IT Services Companies Germany · The Manifest
Models learn patterns from labelled examples. Inaccurate or inconsistent labels lead to inaccurate outputs, which reduces efficiency and increases risk once the model is in use.
Images, video, text, audio and 3D point cloud data, including LiDAR. Typical tasks are object detection, segmentation, entity recognition, sentiment analysis, transcription and speaker identification.
AI-powered tools pre-label the data, and human annotators refine and validate the labels. This speeds up labelling while keeping accuracy high.
Through multi-layered quality control: AI-powered validation, human review and automated consistency checks. We also annotate a sample data set first to validate quality and refine the workflow before scaling up.
Yes. We define annotation goals and guidelines from your model's requirements, so the labelled data matches its learning objectives and integrates with your machine learning pipeline.
Yes. We use cloud-based annotation platforms and automation tools to process high volumes of data with consistent quality.
No. We can help gather and organise raw data, clean it of errors and inconsistencies, and pre-process it before annotation and model development.
Share a few details and our AI team will take it from there. Here is what happens next:
Prefer to pick a time yourself?
Schedule a call